> For the complete documentation index, see [llms.txt](https://docs.maiagent.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.maiagent.ai/tech/ja/quickstart/embedding.md).
# Embedding モデル
## Embedding とは?
RAG(Retrieval-Augmented Generation)の処理において、**Embedding** の中心的な役割は、Parser で処理された文書やナレッジベースのコンテンツなど、大量のテキストデータを、コンピューターが理解して比較できる数値形式、すなわちベクトル(vectors)に変換することです。
この変換により、RAG システムは次のことが可能になります。
### 1. **意味を理解する**
Embedding モデルは、表面的な語彙だけでなく、テキストの深い意味を捉えます。そのため、クエリと文書で使用される表現が異なっていても、意味が近ければ、システムはそれらの関連性を認識できます。
### 2. **効率的に検索する**
テキストをベクトルに変換した後、システムは効率的なベクトル類似度検索アルゴリズムを使用して、大規模なデータベースからユーザーのクエリに最も関連するテキスト部分を迅速に見つけられます。
### 3. **生成品質を向上させる**
検索された関連テキストは、コンテキスト情報として大規模言語モデル(LLM)に提供され、LLM がより正確な回答を生成するのに役立ちます。
## MaiAgent の RAG 技術における Embedding の2つの重要な役割
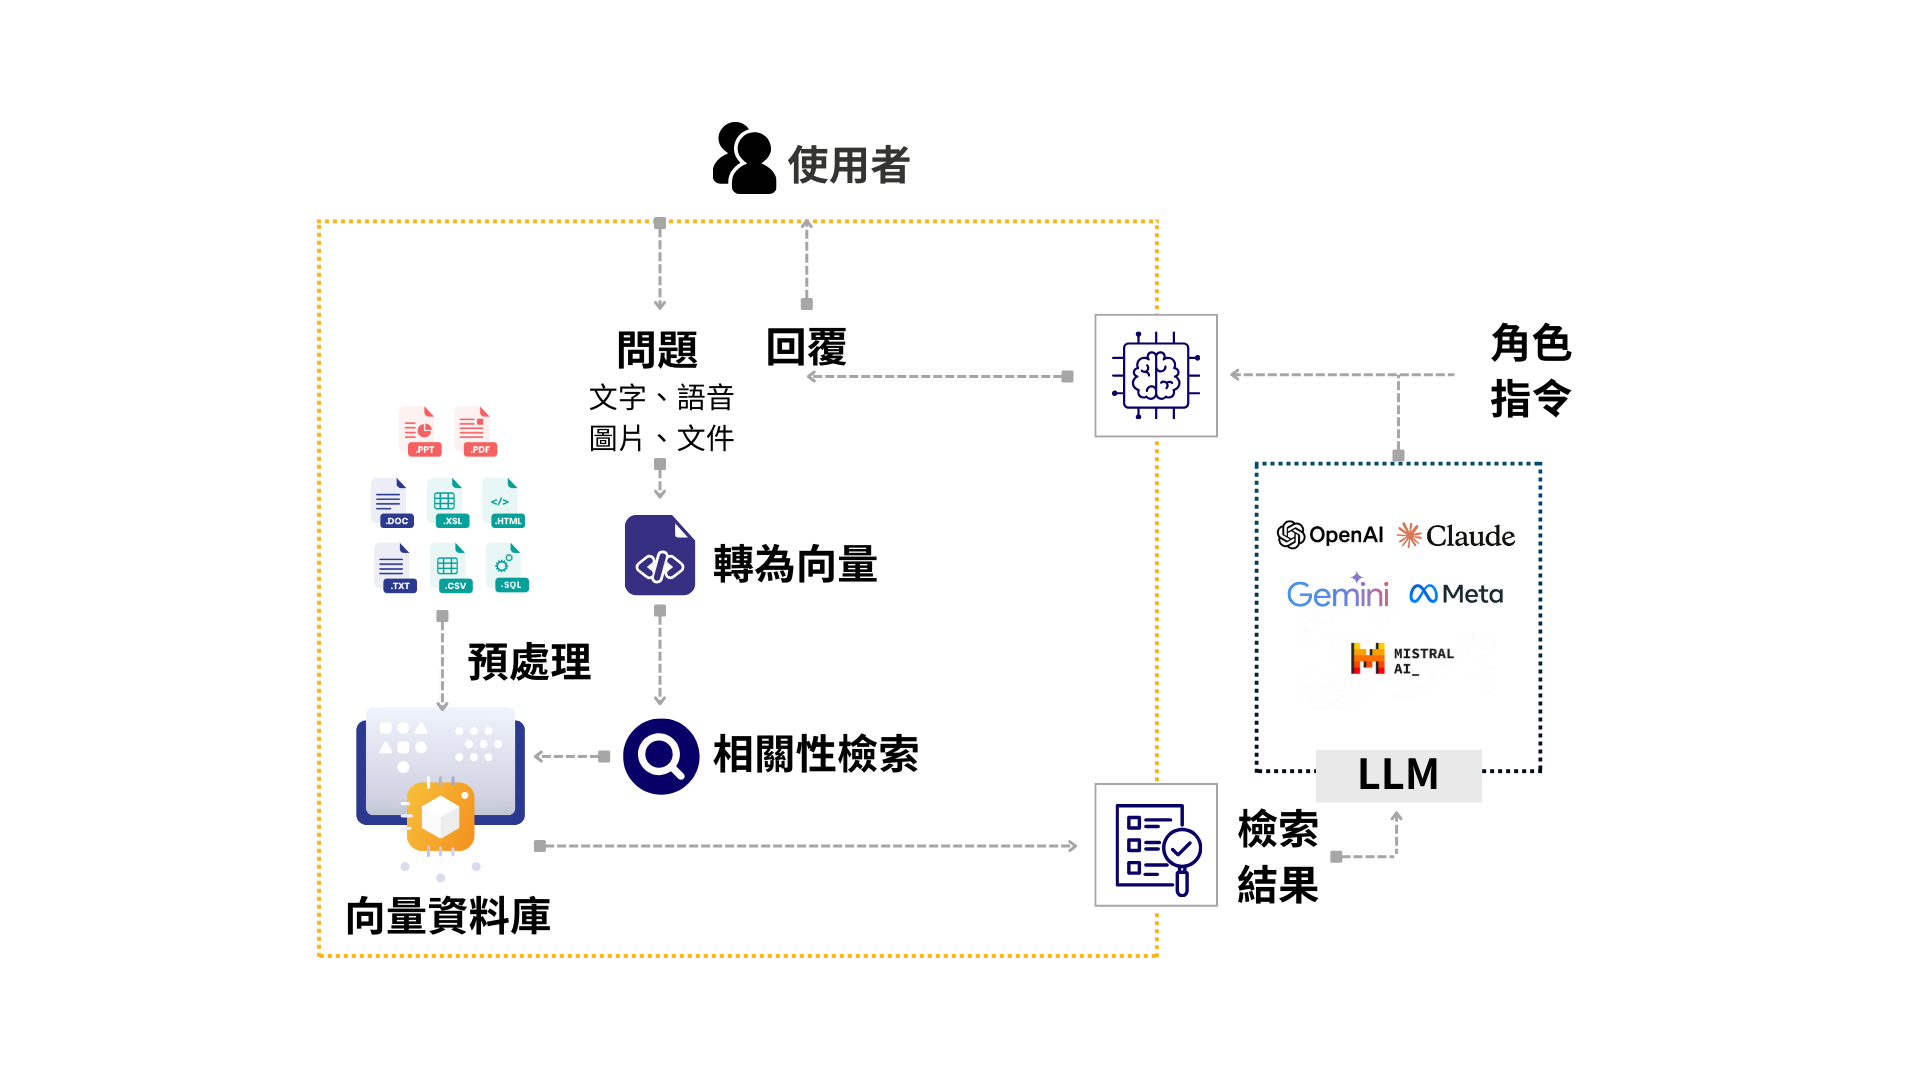
### 1. **ナレッジベースのコンテンツをベクトルに変換し**、ベクトルデータベースに保存します
### 2. **ユーザーの質問をベクトル化し**、データベース内のベクトルと類似度を比較して、最も関連するコンテンツを特定します
RAG の処理フロー
簡単に言えば、Embedding は RAG システムの基盤です。構造化されていないテキストデータを計算・比較可能なベクトルに変換するため、高精度な情報検索と高品質なコンテンツ生成を実現するうえで不可欠な前処理です。
## Embedding が RAG システムに与える影響
### 1. 検索品質
* **意味理解の深さ**:高品質な Embedding モデルはテキストの意味をより正確に捉え、検索の関連性を高めます
* **コンテキスト認識**:優れた Embedding モデルはテキストのコンテキスト関係を理解し、一貫性のある検索結果を実現します
* **多言語対応**:強力な多言語 Embedding モデルは、言語をまたぐナレッジ検索のニーズに対応できます
### 2. システム性能
* **検索速度**:Embedding モデルのベクトル次元数と計算効率は、検索の応答時間に直接影響します
* **リソース消費**:Embedding モデルによって必要なコンピューティングリソースが異なり、システムの拡張性に影響します
* **並列処理**:効率的な Embedding モデルは、大規模な並列検索に対応できます
## MaiAgent が対応する Embedding モデル
| モデル名 | モデル開発元 | 開発国 | 特徴 | オープンソース | デプロイ方式 | MTEB 平均スコア |
| ---------------------------------------- | ------------- | --- | -------------------------------------------------------------------- | ------- | -------------------------------- | ------------------------- |
| Cohere Embed v4.0 | Cohere | カナダ | 多言語対応、最高レベルの性能 | いいえ | クラウド API 推論サービスの利用が必要 | 未公開。v3.0 の 64.47 を参考にできます |
| Cohere Embed Multilingual v3.0 (Bedrock) | Cohere | カナダ | 多言語対応、高性能 | いいえ | クラウド API 推論サービスの利用が必要 | 64.47 |
| OpenAI text-embedding-3-Large | OpenAI | 米国 | 多言語対応(特に英語のコンテキストで高性能)、中程度の性能 | いいえ | クラウド API 推論サービスの利用が必要 | 64.68 |
| EmbeddingGemma | Google | 米国 | オープンソース、多言語対応、軽量 | はい | ニーズに応じてクラウドまたはオンプレミス GPU にデプロイ可能 | 61.15 |
| Mxbai-embed-large | Mixedbread AI | 米国 | オープンソース、性能とリソースのバランスに優れ、長いコンテキストで高性能 | はい | ニーズに応じてクラウドまたはオンプレミス GPU にデプロイ可能 | 64.68 |
| BGE-Large | BAAI | 中国 | オープンソース、多言語対応、軽量 | はい | ニーズに応じてクラウドまたはオンプレミス GPU にデプロイ可能 | 64.23 |
| Nomic-embed-text | Nomic AI | 米国 | オープンソース、軽量 | はい | ニーズに応じてクラウドまたはオンプレミス GPU にデプロイ可能 | 62.39 |
| Qwen3-Embedding 0.6B | Alibaba | 中国 | オープンソース、軽量 | はい | ニーズに応じてクラウドまたはオンプレミス GPU にデプロイ可能 | 61.82 |
| Granite-embedding-278m-multilingual | IBM | 米国 | オープンソース、多言語対応、軽量 | はい | ニーズに応じてクラウドまたはオンプレミス GPU にデプロイ可能 | 56.1 |
{% hint style="info" %}
意味表現の精度と検索の正確性を確保するため、MaiAgent が提供する Embedding モデルは、MTEB(Massive Text Embedding Benchmark)標準に基づいて選定・評価されます。MTEB は現在広く使用されている意味ベクトル化モデルの比較ベンチマークで、次のような多様なタスクを対象としています。
* Retrieval(意味検索)
* Classification(分類)
* Clustering(クラスタリング)
* Reranking(再ランキング)
* STS(Semantic Textual Similarity:意味的テキスト類似度)
* Summarization / QA / Pair Classification など
{% endhint %}
## MaiAgent の Embedding 技術の強み
### 1. 柔軟なモデル選択:
さまざまなニーズに対応する複数の Embedding モデルを提供します
### 2. 多様なデプロイ方式:
クラウドとオンプレミスのデプロイに対応し、データセキュリティを確保します
### 3. パフォーマンス最適化:
RAG のユースケースに合わせて特別に最適化し、最適な検索結果を提供します
### 4. コスト効率:
実際のニーズに応じて適切なモデルを選択し、性能とコストのバランスを取ります
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation dynamically by asking a question.
Perform an HTTP GET request on the current page URL with the `ask` query parameter, and the optional `goal` query parameter:
```
GET https://docs.maiagent.ai/tech/ja/quickstart/embedding.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is optional and describes the broader end goal you are ultimately trying to accomplish on behalf of the user. GitBook uses it to tailor the answer towards what is most useful for that goal.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.