> For the complete documentation index, see [llms.txt](https://docs.maiagent.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.maiagent.ai/tech/en/quickstart/parser.md).
# Parser Tools
Document and speech-to-text parsers for the knowledge base, including supported formats, handling of images and scanned files, offline operation, automatic detection rules, and billing.
## What Is a Parser?
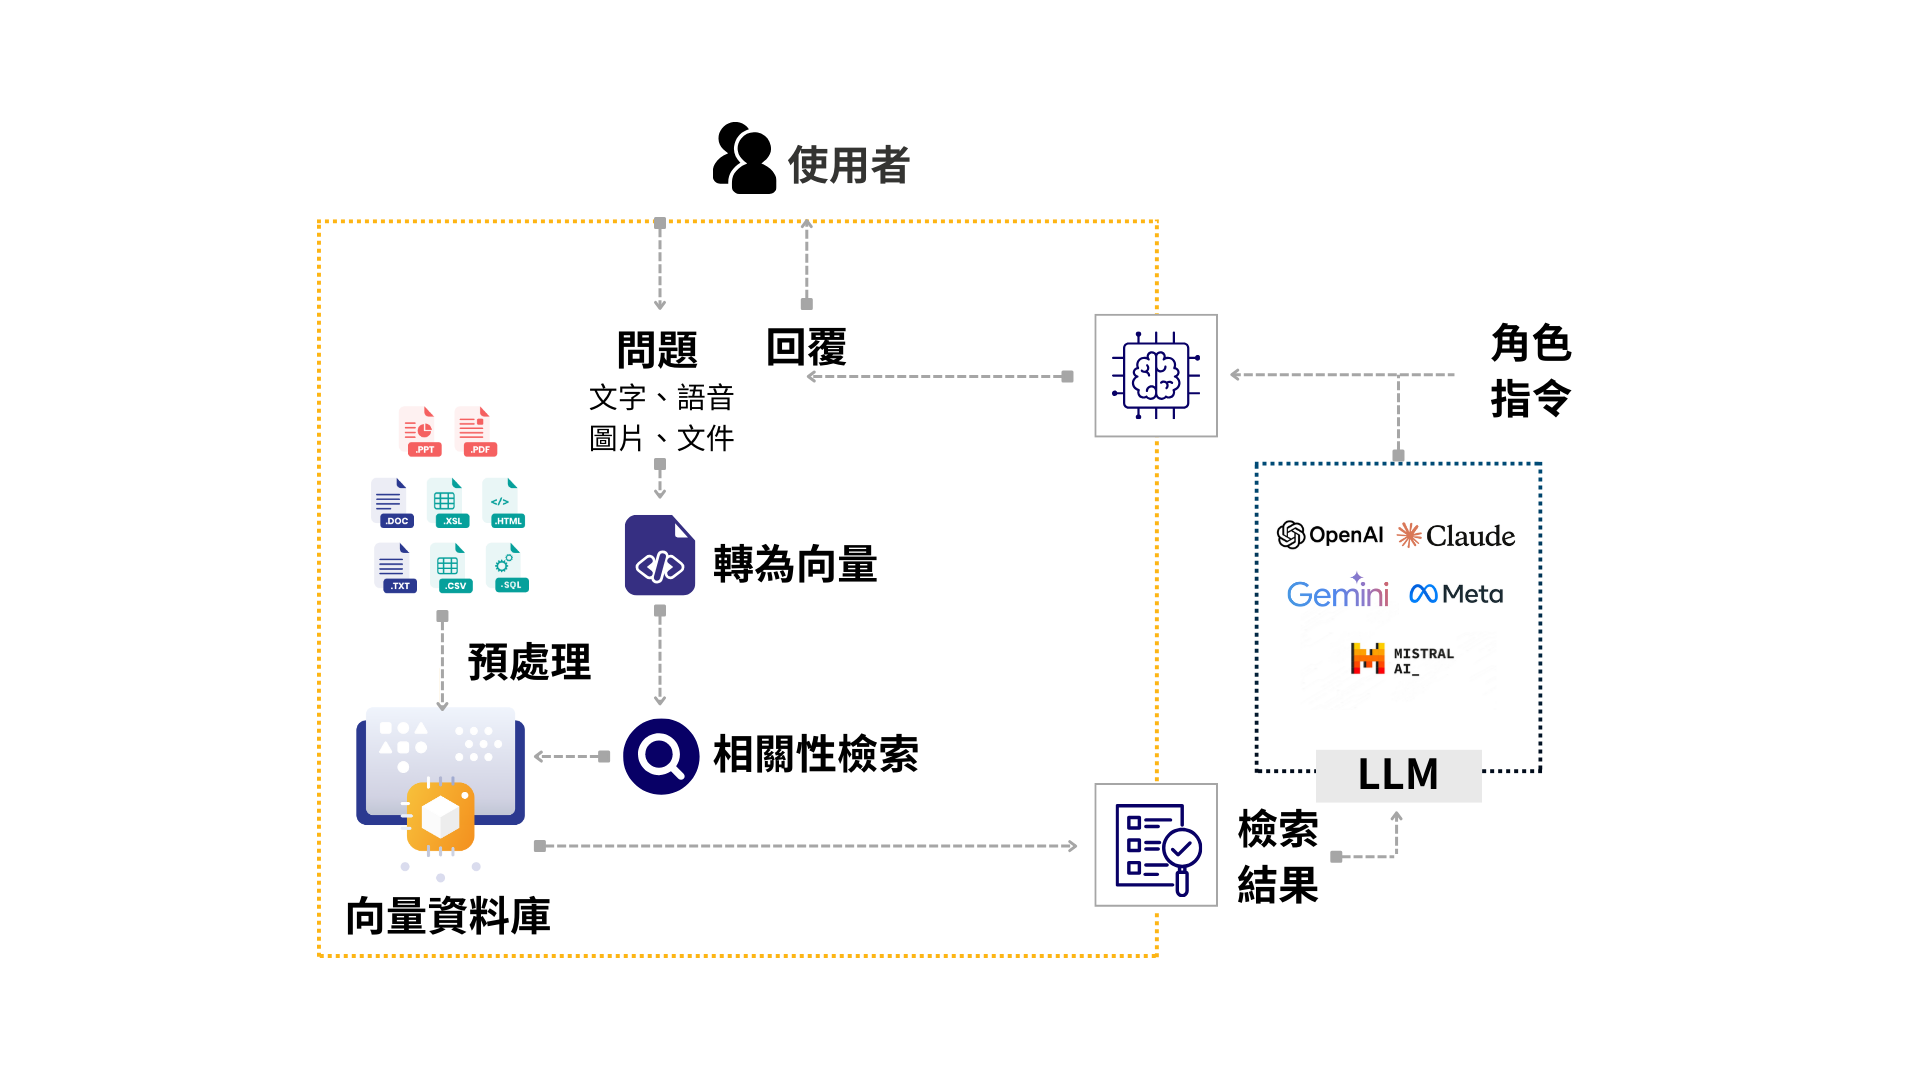
A parser converts raw files uploaded to the knowledge base into text before embedding and retrieval. Parsing quality directly determines whether content can be found later: this step determines whether tables retain their structure and whether text in images and scanned pages is extracted.
RAG workflow
You can specify a parser for each file during upload. For instructions in the admin interface, see [How to Create a Knowledge Base: Basic Settings](https://docs.maiagent.ai/build/knowledge-base/km-basic-settings) in the user manual. You can also call `GET /api/v1/allowed-file-specs/` to retrieve the file types supported by each parser.
***
## Document Parsers
MaiAgent Cloud currently provides three document parsers:
| Item | MaiAgent Parser (default) | MaiAgent Parser (Offline) | Vision Parser |
| --------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------ | --------------------------------------------------------------------------------------------------- |
| Processing method | Reads text, tables, and images directly from the file | Uses layout analysis to preserve document structure (headings and tables) | Uses a cloud multimodal model to visually read the document page by page and convert it to Markdown |
| Images and scanned pages | Extracts embedded images; performs OCR on vector drawing pages without a text layer | Adds OCR and image descriptions for PDFs when a multimodal model is configured | Uses visual understanding to read content in images, charts, and scanned pages |
| Uses a large language model | No | Only when a multimodal model is configured | Yes |
| Offline (no network) environments | Supported | Supported; image descriptions require an on-premises multimodal model | Not supported; requires a connection to a cloud model |
| Supported formats | `.pdf` `.doc` `.docx` `.odt` `.xls` `.xlsx` `.csv` `.ods` `.ppt` `.pptx` `.odp` `.epub` `.txt` `.json` `.jsonl` `.md` `.eml` and image files `.png` `.jpg` `.jpeg` `.gif` `.webp` `.tiff` | `.pdf` `.docx` `.pptx` `.md` `.html` `.htm` | `.pdf` `.doc` `.docx` `.odt` `.ppt` `.pptx` `.odp` |
* To add **image files** (`.png`, `.jpg`, etc.) to a knowledge base, the knowledge base must use an Embedding model that supports multimodal input. See [Embedding Models](/tech/en/quickstart/embedding.md#before-you-choose).
* MaiAgent Parser (Online) is currently disabled platform-wide and cannot be selected.
* Available parsers for on-premises deployments depend on deployment settings. Contact your MaiAgent representative.
#### Gemini Vision Parser
In addition to the three parsers above, the platform can enable a parser that uses **Gemini 3.1 Pro Preview** (via Google Vertex AI) for image recognition (OCR). It supports the same formats as Vision Parser (`.pdf` and Word, PowerPoint, and OpenDocument files; Office files are first converted to PDF).
| Item | Description |
| ------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Processing method | Sends the entire PDF to the model at once, without splitting it into individual pages |
| Per-file limit | 50 MB or 1,000 pages |
| If recognition of the entire document fails | Automatically retries in batches of 50 pages |
| Billing | Charges Credits based on actual model input and output usage, recorded in usage history as `Vision parsing input: filename` and `Vision parsing output: filename` |
| Offline (no network) environments | Not supported; requires a connection to Vertex AI |
The default parser and the selection rules for “Auto-detect (default)” remain unchanged. When needed, select this parser manually from the Parser dropdown in the upload window or document list. The parser list is configured by the platform. If this option is unavailable, contact your MaiAgent representative.
#### “Auto-detect (Default)” and Parsing Billing
When you upload PDF, Word (.docx), or PowerPoint (.pptx) files to the knowledge base, the parser dropdown next to each file in the upload window defaults to Auto-detect (default), rather than always using MaiAgent Parser. After upload, the system reads the file structure to choose a parser:
* Files containing only text, with no significant image content → Use the default parser for that file type (usually MaiAgent Parser).
* Scanned files (without a text layer), files containing image content (such as engineering drawings and scans), and PowerPoint files → The system selects a parser that supports OCR or visual understanding (MaiAgent Parser (Offline) or Vision Parser). If no suitable parser is found, it uses the default parser.
The decision is based on file structure (whether a text layer exists and the number of pages containing images or tables), rather than the number of images. Word files with any embedded images are treated as containing image content. Documents with only a few images may therefore still switch to one of the parsers above. The parser shown in the Parser column of the knowledge base document list is the actual parser used.
Credits are calculated based on **the parser that actually completes parsing**. For each parser's billing units and rules for reparsing and switching parsers, see [Usage Calculation: Billing Units for Each Parser](https://docs.maiagent.ai/others/usage#parser-billing-units) in the user manual. For reconciliation, each parsing charge is recorded in the organization's Credits Usage History with the descriptions below (the “Description” column in exported CSV files; you can also enter a filename in Search to look it up):
| Parser | Description in usage history |
| ------------------------- | ------------------------------------------------------------------- |
| MaiAgent Parser | `Document parsing (maiagent): filename` |
| MaiAgent Parser (Offline) | `Document parsing (docling): filename` |
| Vision Parser | `Vision parsing input: filename`, `Vision parsing output: filename` |
{% hint style="warning" %}
Changing the parser in the document list (including Bulk Change Parser) immediately reparses the document without a confirmation dialog. To keep parsing costs predictable and prevent automatic switching to other parsers, select MaiAgent Parser (or another specified parser) directly during upload instead of using Auto-detect (default).
{% endhint %}
#### Parsing Failures Caused by Oversized Images
Embedded images in documents have size limits. Exceeding them produces one of two outcomes, depending on the parser:
* **Vision Parser** skips embedded images with a side longer than 8,000 px or a total pixel count (width × height) greater than 40 million, and recognizes only the full-page image. This does not cause the entire document to fail. If the skipped image contains important content, resize it before uploading again.
* **Other parsers** may fail on the entire document when decoding oversized images. The Failure Reason in the document list may show a message such as `total decoded image size must be at most … pixels`, indicating that an image in the document exceeds the parser's decoding limit for total pixels. To resolve this, resize or compress images in the source document and upload it again; switch to Vision Parser for scanned files; or, if you only need text, save a version of the document without images first.
{% hint style="info" %}
The limit is based on total pixels, not file size: an 8,000 × 8,000 screenshot (64 million pixels) exceeds it even when compressed into a small JPEG. Keeping the longer side within 4,000 px is the safest approach when resizing.
{% endhint %}
***
## Speech-to-Text Parsers
After an audio file is uploaded to the knowledge base, a speech-to-text parser converts it into a transcript, which is then indexed. MaiAgent Cloud currently provides:
| Parser (name in the admin interface) | Service | Language settings | Custom prompts | Video uploads supported |
| ------------------------------------ | ----------------------- | --------------------------------------------------------------------------- | -------------- | ----------------------- |
| Azure Speech | Azure Speech service | Specify up to 4 languages | No | No |
| WhisperGroq | Groq (Whisper large-v3) | Specify 1 language or auto-detect | Yes | Yes |
| WhisperOpenAI | OpenAI (Whisper) | Specify 1 language or auto-detect | Yes | Yes |
| Bronci (長問語音辨識) | Bronci | Choose 1: Taiwanese Hokkien, Taiwanese Mandarin, or Hakka (Sixian or Hailu) | No | No |
Speech-to-text is billed by audio duration in seconds, and each retranscription incurs another charge. See [Usage Calculation: Billing Units for Each Parser](https://docs.maiagent.ai/others/usage#parser-billing-units) in the user manual. The description in usage history is `Audio parsing (service code): filename`, for example, `Audio parsing (azure): filename`.
Speech-to-text for on-premises deployments is configured by the deployment package. New deployments use the local LocalAI service by default (with Qwen3-ASR or Whisper, requiring a GPU), while existing sites can continue using Whisper (Offline). Both run on-premises, and audio is not sent to the cloud.
After audio parsing completes, you can view the transcript in the knowledge base and download it as TXT (plain text) or SRT (subtitle format):
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.maiagent.ai/tech/en/quickstart/parser.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.