> For the complete documentation index, see [llms.txt](https://docs.maiagent.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.maiagent.ai/tech/en/platform-development/gpu.md).

# GPU Compute Hardware Planning

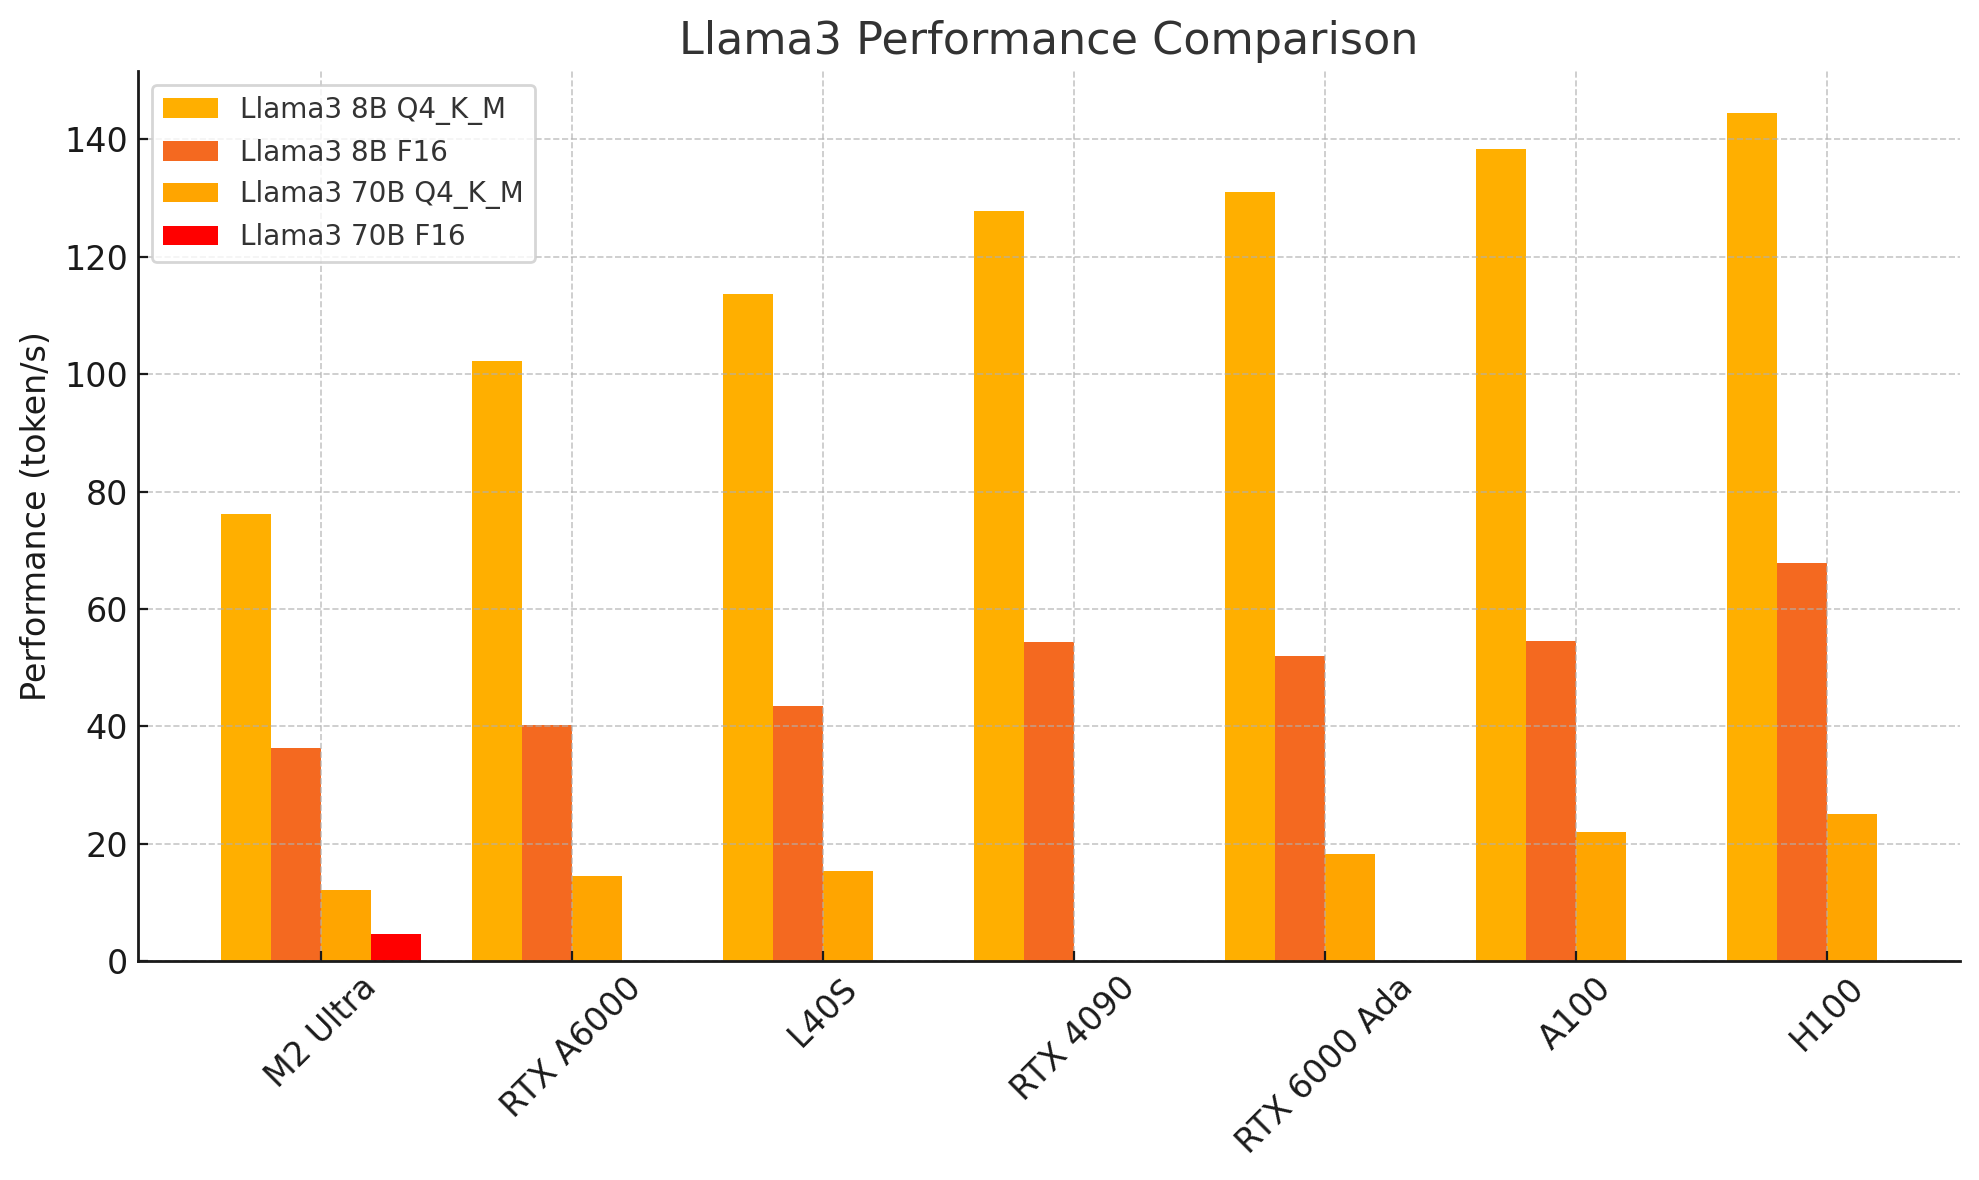
## Llama3 Inference Speed on GPUs (tokens/second)

<figure><img src="https://3415477754-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FNBTi475lqozGpB7xObpE%2Fuploads%2Fgit-blob-48ab072976455e9efd6b67df1b515038a3732e43%2Foutput%20(4).png?alt=media" alt=""><figcaption><p>Performance Comparison of Mainstream GPUs on Llama3 8B / 70B</p></figcaption></figure>

<table><thead><tr><th width="166">GPU</th><th width="145">Memory(VRAM)</th><th width="125">8B Q4_K_M</th><th width="89">8B F16</th><th width="129">70B Q4_K_M</th><th width="159">70B F16</th></tr></thead><tbody><tr><td>RTX 4090</td><td>24GB</td><td>127.74</td><td>54.34</td><td>Out of Memory</td><td>Out of Memory</td></tr><tr><td>RTX A6000</td><td>48GB</td><td>102.22</td><td>40.25</td><td>14.58</td><td>Out of Memory</td></tr><tr><td>L40S</td><td>48GB</td><td>113.60</td><td>43.42</td><td>15.31</td><td>Out of Memory</td></tr><tr><td>RTX 6000 Ada</td><td>48GB</td><td>130.99</td><td>51.97</td><td>18.36</td><td>Out of Memory</td></tr><tr><td>A100</td><td>80GB</td><td>138.31</td><td>54.56</td><td>22.11</td><td>Out of Memory</td></tr><tr><td>H100</td><td>80GB</td><td>144.49</td><td>67.79</td><td>25.01</td><td>Out of Memory</td></tr><tr><td>M2 Ultra</td><td>192GB</td><td>76.28</td><td>36.25</td><td>12.13</td><td>4.71</td></tr></tbody></table>

***

## VRAM Requirements for Llama3 Models

| Model      | Q4\_K\_M (Quantized) | F16 (Original) |
| ---------- | -------------------- | -------------- |
| Llama3 8B  | 4.58 GB              | 14.96 GB       |
| Llama3 70B | 39.59 GB             | 131.42 GB      |

Source

{% embed url="<https://github.com/XiongjieDai/GPU-Benchmarks-on-LLM-Inference>" %}

***

## Hardware Configuration Recommendations

MaiAgent recommends two combinations suitable for different groups:

1. **Two H100(80GB)**: Higher budget, prioritizing quality and performance
2. **L40S(48GB) and RTX 6000 Ada(48GB)**: Standard budget, focusing on cost-effectiveness

For more detailed information, please contact MaiAgent's professional consultants at <mark style="color:blue;"><sales@maiagent.ai></mark>


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation dynamically by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://docs.maiagent.ai/tech/en/platform-development/gpu.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `build a script that syncs our docs to a CMS` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.
