> For the complete documentation index, see [llms.txt](https://docs.maiagent.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.maiagent.ai/tech/en/quickstart/rag.md).
# RAG Knowledge Retrieval System
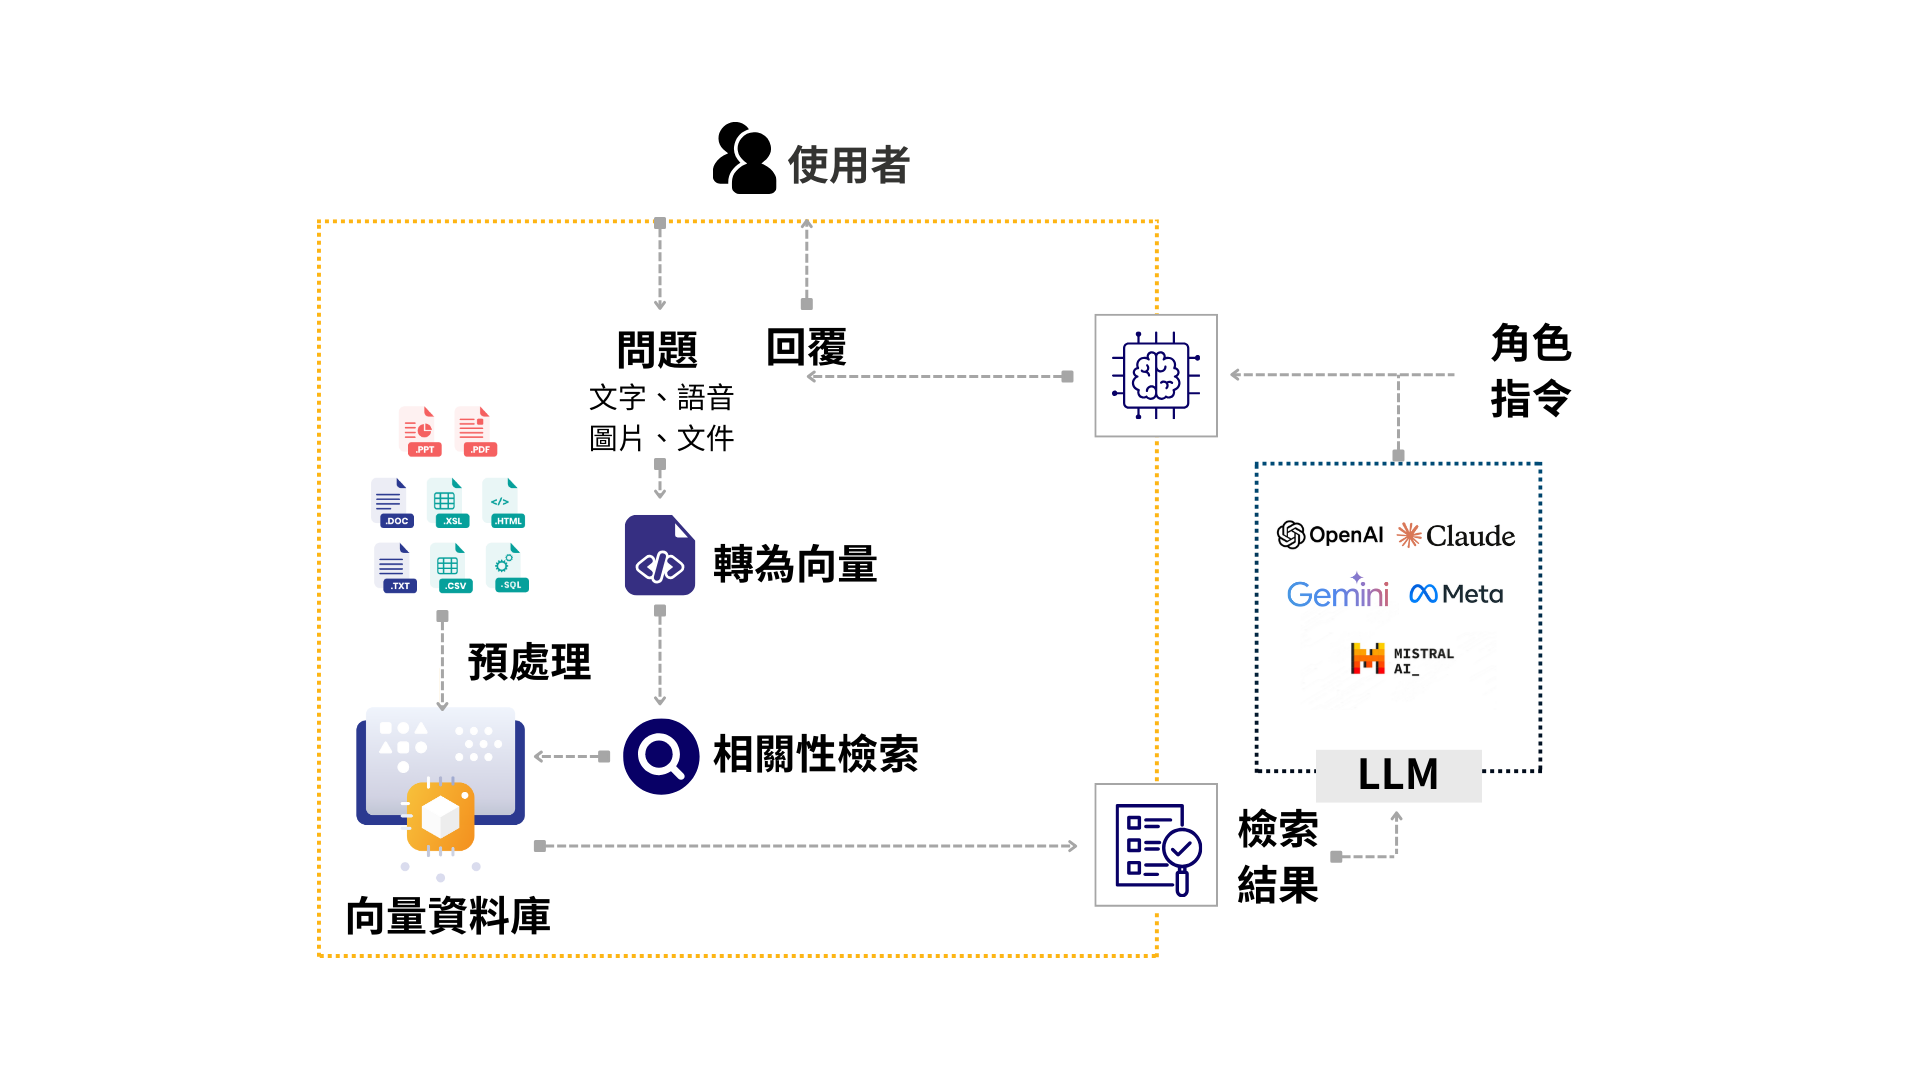
RAG (Retrieval-Augmented Generation) retrieves relevant passages from a knowledge base before passing them to a large language model to answer questions. This page explains MaiAgent's data processing
RAG (Retrieval-Augmented Generation) lets a large language model retrieve passages relevant to a question from a knowledge base before answering based on those passages. This allows the model to reference the organization's own documents instead of relying solely on training data.
RAG workflow
Think of RAG as an open-book exam: the model does not need to memorize all the data. Before each answer, it looks through the knowledge base for the passages most relevant to the question and uses them as evidence. For this reason, it is best to include only data relevant to the Agent's tasks in the knowledge base. Irrelevant content may still be retrieved as context and make answers less accurate.
This page explains MaiAgent's actual processing workflow and configurable parameters. For instructions in the admin interface, see [Knowledge Base Overview](https://docs.maiagent.ai/build/knowledge-base/km) in the user manual.
## How Data Enters the Knowledge Base
Files uploaded to the knowledge base go through these steps in order:
1. **Parsing**: A parser converts the file into text (including tables and images when needed). See [Parser Tools](/tech/en/quickstart/parser.md).
2. **Chunking**: Text is split into passages (chunks), which serve as the units for retrieval and citations.
3. **Embedding**: The Embedding model selected for the knowledge base converts each passage into a vector. See [Embedding Models](/tech/en/quickstart/embedding.md).
4. **Writing to the vector database**: Passage text and vectors are written together to a vector database. The platform's built-in database is used by default, but you can connect your own. See [Bring Your Own Vector Database](/tech/en/platform-development/bring-your-own-vector-db.md).
Content becomes retrievable only after the file status changes to `done`.
## The Workflow for a Single Retrieval
### 1. Determine the Retrieval Scope
Before retrieval, the platform determines which knowledge bases, files, and labels can be queried and applies these conditions directly to the vector database query. Passages outside this scope are never retrieved and therefore never reach the model.
The scope is taken in order from: message → conversation → contact's Query Metadata. If none of these is configured, the Agent's default label filter applies. If no filter is configured either, the entire knowledge base is queried. For setup instructions, see [Query Metadata Overview](/tech/en/identity-and-access/zhi-shi-guan-li-quan-xian-query-metadata-cha-xun-yuan-zi-liao-zong-lan.md) and [Knowledge Base Label Filtering](https://docs.maiagent.ai/build/agent/label-filter) in the user manual.
{% hint style="warning" %}
To restrict who can see which documents, use Query Metadata or label filtering instead of relying solely on the system prompt. The system prompt is text provided to the model after retrieval and cannot block passages that have already been retrieved.
{% endhint %}
### 2. Hybrid Search
By default, **hybrid search** runs two types of queries simultaneously:
* **Vector search**: Uses the question's vector to find semantically similar passages, even when the wording differs.
* **Keyword search (BM25)**: Matches words and terms, making it useful for product model numbers, proper nouns, and codes.
When Enable Reciprocal Rank Fusion (RRF) is turned on for the knowledge base, the two sets of results are merged by rank using RRF. Using RRF on Elasticsearch requires an Enterprise, Platinum, or Trial license. If your own Elasticsearch instance lacks such a license, the admin interface automatically disables this option. When hybrid search is disabled on the platform, only vector search is used.
Agent conversations always follow the platform's retrieval settings and cannot select a separate mode. However, [Search Testing](https://docs.maiagent.ai/build/knowledge-base/test-search-result#search-modes) in the admin interface and the [Knowledge Base Retrieval API](/tech/en/api-integration/knowledge-base-api.md#search-knowledge-base) let you specify vector-only (Semantic Search, `semantic`) or keyword-only (Keyword Search, `keyword`, Elasticsearch only) retrieval to compare what each method finds.
### 3. Reranking with Reranker
When Enable Search Result Reranking (Reranking) is turned on for the knowledge base, the first stage retrieves extra candidate passages (Number of Retrieved Chunks × the platform's configured multiplier, 7 by default). The Reranker model then compares the question with each passage, rescores them, and retains only the highest-scoring Number of Retrieved Chunks results. See [Reranker Models](/tech/en/quickstart/reranker.md).
If the organization's Credits fall below the platform threshold, that conversation skips Reranker and uses the first-stage results directly.
### 4. Similarity Threshold
The Similarity Threshold (0–1) filters out passages whose Reranker scores fall below the threshold. The default is 0, meaning no filtering. Because the threshold applies to Reranker scores, **it only takes effect when Reranker is enabled**. Setting it too high may remove every passage, leaving the model without reference material.
### 5. Merge Results from Multiple Knowledge Bases
When an Agent has multiple knowledge bases attached, their results are merged. The Agent's Maximum Number of Retrieved Blocks then determines how many passages are ultimately sent to the model. If any knowledge base queried in this retrieval has Reranker enabled, the merged results are reranked once more.
### 6. Send to the Model and Add Citations
The selected passages are sent to the large language model along with the Agent's system prompt. If Use During Retrieval is checked for a file metadata field, that field's value is also sent to the model as reference information for answering. Citations in the response link back to the source passages and files.
## Agentic RAG: Retrieval in Agent Mode
The workflow above performs “one retrieval, one generation”: each message always triggers retrieval before an answer, and the model does not decide whether or what to search for. Agentic RAG lets the model decide how to retrieve. While answering, it can call retrieval multiple times, adjust queries based on earlier results, change keywords, or read another file before composing an answer.
In MaiAgent, these approaches correspond to the Agent's reply modes:
| Reply mode | Retrieval method |
| ----------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| RAG Q\&A (`replyMode: normal` in the API) | Single retrieval: each message triggers one retrieval using the workflow on this page, and passages are sent directly to the model |
| Agent mode (`replyMode: agent`) | Agentic RAG: the knowledge base is provided to the model as tools. Within one turn, the model can retrieve passages multiple times, filter files by filename or metadata, search file contents by keyword, and read entire files. Each call follows the retrieval workflow on this page (including Query Metadata scope restrictions) |
The number of retrieval rounds in Agent mode is constrained by the Agent's execution limits (see [Function Calling: Execution Limits](/tech/en/advanced-genai-tech/function-calling.md#limits)), and latency and usage are higher than with a single retrieval. RAG Q\&A is sufficient for Q\&A scenarios where the answer is in a single passage. Use Agent mode for scenarios that require comparing multiple documents or finding a file before reading it closely.
## How Chat Mode and Agent Mode Query the Knowledge Base
Building on the previous section, the differences between the two modes are compared below:
| | RAG Q\&A (chat mode, `replyMode: normal`) | Agent mode (`replyMode: agent`) |
| --------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| When retrieval occurs | **Always** retrieves once before answering each message, without a model decision | Retrieval is a **tool**; the model decides whether to call it, how many times, and which query string to use |
| How many results are retrieved | Each knowledge base retrieves its own Number of Retrieved Chunks; merged results are truncated according to the Agent's Maximum Number of Retrieved Blocks | The model supplies `top_k` for the `retrieve_text_nodes` tool (default 3), so it usually retrieves fewer than the configured number of chunks. When Force Full Retrieval Scope is checked for the Agent, Maximum Number of Retrieved Blocks is always used instead |
| Available tools | None; only the passages retrieved this time | `retrieve_text_nodes` (semantic/hybrid retrieval), `query_files` (lists files and metadata), `grep_files` (matches strings in file contents), `read_file` (reads entire files), `get_surrounding_context` (retrieves surrounding passage context), `image_search` (finds images in multimodal knowledge bases; can be disabled in tool settings) |
| Query Metadata, label filtering, Reranker, similarity threshold | Apply to both modes under the same rules | |
| Attachments uploaded in the conversation | Parsed and indexed immediately on upload, then retrieved alongside the knowledge base when answering, using the Agent's maximum number of retrieved blocks | Not parsed on upload; the Agent uses attachment tools (`parse_attachment_content`, `read_attachment_full_text`, `ingest_attachment`) to read or index them according to the question. See [How Message Attachments Are Processed](/tech/en/api-integration/api_knowledge.md#attachment-processing) |
| When search results are unsatisfactory | Adjust knowledge base parameters and the Agent's maximum number of retrieved blocks | First check whether the model called retrieval tools (inspect tool calls in [Conversation Details and Execution Timeline](https://docs.maiagent.ai/build/agent-ops/evaluations/trace-timeline)), then adjust parameters or require knowledge base retrieval in the system prompt |
{% hint style="warning" %}
When Enable Tool Search (dynamic tool search) is turned on for the Agent, knowledge base tools are also in the pool that must be searched before loading. Like Text to SQL and API tools, they require a call to `tool_searching_tool` first. The model may occasionally skip the search, answer that “no knowledge base retrieval tool is available,” and use only other tools. If this happens, explicitly state in the system prompt: “Query the knowledge base with `retrieve_text_nodes` before answering,” or disable tool search to make all tools directly available. Attaching a knowledge base does not automatically trigger retrieval, and you do not need to create a separate retrieval tool.
{% endhint %}
## Configurable Parameters
| Parameter | Setting location | Default | Description |
| --------------------------------------------------------------------------- | ---------------- | ---------------- | ------------------------------------------------------------------------------------------------------------------------------------------- |
| Embedding Model | Knowledge base | Platform setting | Cannot be changed in the admin interface after creation; create another knowledge base or contact your MaiAgent representative to change it |
| Number of Retrieved Chunks | Knowledge base | 12 | Maximum number of passages retrieved from each knowledge base; minimum 1 |
| Enable Search Result Reranking (Reranking) | Knowledge base | Enabled | Uses the Reranker model selected for the knowledge base when enabled |
| Similarity Threshold (0–1) | Knowledge base | 0 | Takes effect only when Reranker is enabled |
| Enable Reciprocal Rank Fusion | Knowledge base | Platform setting | Method for merging hybrid search results; must be enabled for hybrid search on OpenSearch |
| Maximum Number of Retrieved Blocks | Agent | 12 | Number of passages ultimately sent to the model during a conversation; the interface recommends 5–15, and higher values increase latency |
To check which passages a question retrieves, use [Search Testing](https://docs.maiagent.ai/build/knowledge-base/test-search-result) in the admin interface or call the [Knowledge Base Retrieval API](/tech/en/api-integration/knowledge-base-api.md#search-knowledge-base).
### How to Tune
Chunk size and overlap are determined by the parser and cannot be adjusted through fields in the admin interface. You can adjust the parameters below. Change only one at a time and compare results in Search Testing with the same set of questions.
| Symptom | Check first | Then adjust |
| -------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| The correct passage is found but ranks too low or is truncated | Its ranking in Search Testing | Enable Reranker; if that is insufficient, increase the number of retrieved chunks and maximum number of retrieved blocks (latency and token usage will increase) |
| Irrelevant passages are frequently included | Passage order after enabling Reranker | Raise the similarity threshold (by 0.05–0.1 at a time; too high removes all results), or narrow the scope with label filtering |
| Model numbers, codes, or proper nouns cannot be found | Whether keyword search finds them | Ensure the document uses the same wording as the user; re-enable hybrid search if disabled (Elasticsearch requires an RRF license) |
| Answers cover only part of a table or long document | Whether chunks split the table | Reparse with a different parser, add table headers or section names within chunks, or enable Force Full Retrieval Scope for the Agent |
| Answers use only attachments and ignore the knowledge base (or vice versa) | Tool call logs in Agent mode | Explicitly require knowledge base retrieval first in the system prompt; chat mode retrieves both together, so increase the maximum number of retrieved blocks |
| Reranker is enabled but has no effect | Whether the organization's Credits are below the platform threshold (which automatically skips Reranker) | Top up Credits first, then compare |
The Embedding model cannot be changed after creation; changing models means rebuilding the knowledge base. Compare results from different models in Search Testing before going live and making your final choice.
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.maiagent.ai/tech/en/quickstart/rag.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.