> For the complete documentation index, see [llms.txt](https://docs.maiagent.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.maiagent.ai/maiagent-user-guide/en/build/knowledge-base/scrape-website.md).

# Use the Web Crawling Feature

Enter a URL, set the crawl scope, and choose a one-time run or recurring schedule. MaiAgent automatically crawls the pages and imports them into your knowledge base, with each import result available

## Purpose and Value <a href="#feature-purpose-and-value" id="feature-purpose-and-value"></a>

As an employee, you may often be asked by your manager to consult or compile regulatory information from public websites, or to help an Agent stay up to date with the latest products and FAQ content on your company's website.

If you have a technical background or help from engineers, you could write a crawler to collect the data automatically. For nontechnical staff, however, this usually means organizing pages manually, one by one—a time-consuming task that can easily miss key information.

MaiAgent's crawler lets you do the following without writing code (No-Code):

* **Crawl an entire website scope at once**: Set the crawl depth, page limit, and URL rules to determine which pages to crawl
* **Run once or on a recurring schedule**: Crawl immediately, or automatically crawl again daily, weekly, or monthly
* **Automatically import into a knowledge base**: Import directly into a selected knowledge base after crawling, with options to skip, overwrite, or allow duplicates when a URL already exists
* **Track import results**: View the number of successfully imported and failed pages for each import in the import history

## Use Case <a href="#use-case" id="use-case"></a>

A company's customer service manager wants the AI customer service agent's answers to match the FAQ on the company website. She first creates a knowledge base dedicated to the website FAQ, then opens “Crawler” to create a crawl request. She enters the FAQ URL and sets a small maximum crawl depth and page limit to check that only FAQ-related pages will be crawled. She selects “Scheduled Run,” sets it to every Monday at 9 a.m., selects the new knowledge base as the automatic import destination, and chooses “Skip” for existing URLs. Once created, this weekly synchronization task appears on the Schedules tab. After each crawl, she can check “Import History” in the crawl request details to see which knowledge base received the automatic import and how many pages succeeded or failed. When the website FAQ changes, she no longer needs an engineer to organize the data.

## How to Crawl <a href="#how-to-scrape" id="how-to-scrape"></a>

{% hint style="info" %}
If “Crawler” does not appear in the left menu, your account does not have crawler access. Contact your organization administrator to check your permissions.
{% endhint %}

### 1. Open the Crawler Page <a href="#open-crawler" id="open-crawler"></a>

In the left menu, click <mark style="color:blue;">AI Features</mark> → <mark style="color:blue;">Crawler</mark>. The page has two tabs:

* <mark style="color:blue;">Page Crawl Requests</mark>: Lists each crawl, including one-time runs and crawls created by each automatic scheduled run. Search by name or URL, and filter by type (one-time/scheduled) and crawl status (completed/in progress/failed)
* <mark style="color:blue;">Schedules</mark>: Lists all recurring crawl schedules

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-e4539a8db7b766461e78291d443ecd5bdab3035f%2Fcrawl-list-requests.png?alt=media" alt="The Page Crawl Requests tab on the crawler page lists one completed one-time crawl, with Details, Import, and View in the actions column"><figcaption><p>Page Crawl Requests tab: Each request shows its type, crawl status, and creation time</p></figcaption></figure>

### 2. Enter a Task Name and URL <a href="#step-url" id="step-url"></a>

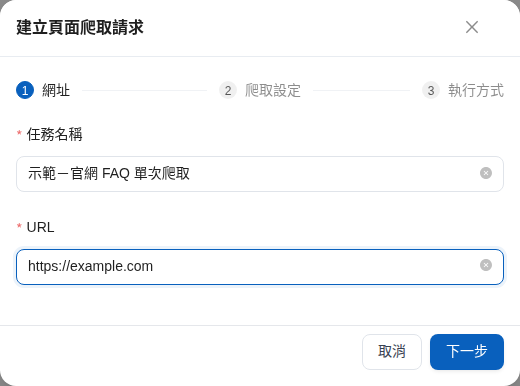
Click <mark style="color:blue;">Create Page Crawl Request</mark> in the upper right. The creation process has three steps: “URL,” “Crawl Settings,” and “Execution Method.”

In the first step, enter:

* <mark style="color:blue;">Task Name</mark>: A name that helps you identify this crawl task, such as “Daily Product Page Crawl”
* <mark style="color:blue;">URL</mark>: The URL where crawling should start

Then click <mark style="color:blue;">Next</mark>.

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-90d847c058b16aa2555db9acbfb4deb8cb91d7df%2Fcrawl-create-url.png?alt=media" alt="The first step of the Create Page Crawl Request dialog, with fields for task name and URL"><figcaption><p>Step 1: Enter the task name and starting URL</p></figcaption></figure>

### 3. Set Crawl Depth and Scope <a href="#step-crawl-settings" id="step-crawl-settings"></a>

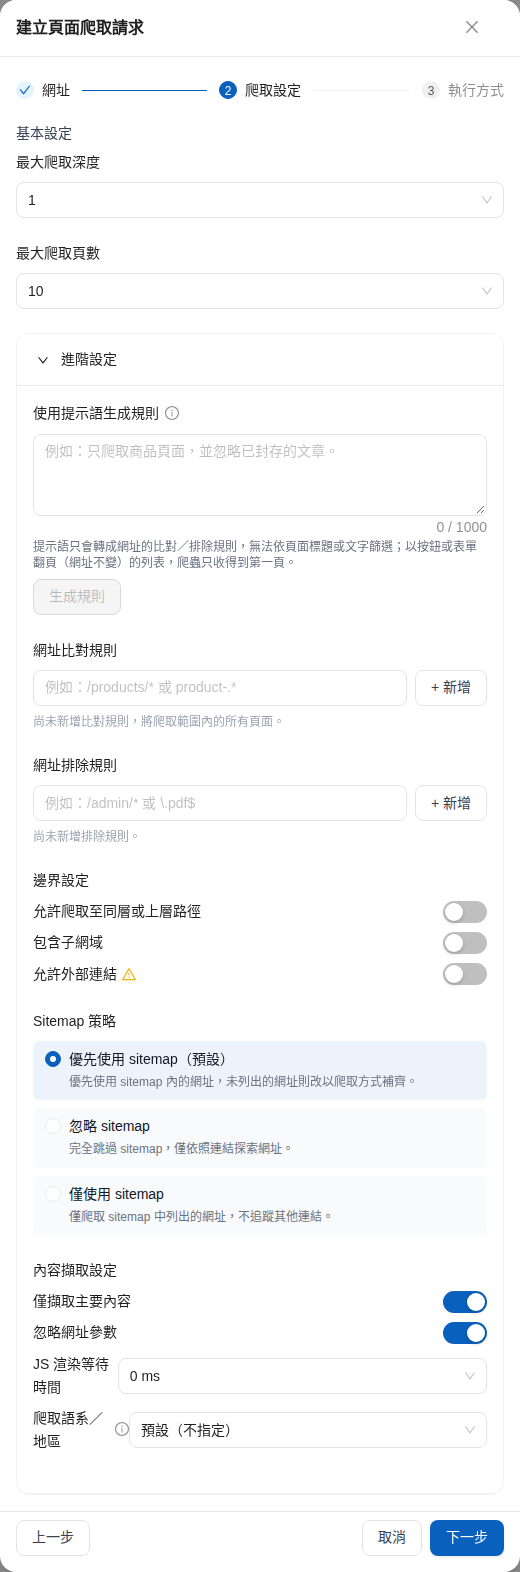
The second step, “Crawl Settings,” determines how many pages to crawl. <mark style="color:blue;">Basic Settings</mark> has two fields:

| Field                                                   | Description                                                                                            |
| ------------------------------------------------------- | ------------------------------------------------------------------------------------------------------ |
| <mark style="color:blue;">Maximum Crawl Depth</mark>    | The number of levels of links to follow from the starting URL. Choose 1–10; the default is 2           |
| <mark style="color:blue;">Maximum Pages to Crawl</mark> | The maximum number of pages for this crawl. Choose 10, 50, 100, 500, 1000, or 5000; the default is 100 |

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-b8322b7180855f80945e61f82f8859bbf5c5a8bb%2Fcrawl-create-basic-settings.png?alt=media" alt="Basic Settings in the Crawl Settings step, with maximum crawl depth set to 1 and maximum pages to crawl set to 10"><figcaption><p>Basic Settings: Control the crawl scope with maximum crawl depth and maximum pages to crawl</p></figcaption></figure>

For more precise control over the scope, expand <mark style="color:blue;">Advanced Settings</mark>:

| Setting                                                       | Description                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                  |
| ------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| <mark style="color:blue;">Generate Rules from a Prompt</mark> | Describe which URLs to collect in natural language (for example, “Only crawl product pages and ignore archived articles”). Click <mark style="color:blue;">Generate Rules</mark> to have AI convert the prompt into the URL matching and exclusion rules below. You can still edit each rule afterward. Enter a URL in the first step before generating rules. If the prompt cannot be mapped to URL rules, you will see “Only URL-based filtering is currently supported”; rewrite the prompt or add rules manually. If you continue without clicking Generate Rules, a confirmation appears first; see “[Confirmation When a Prompt Has Not Generated Rules](#prompt-not-generated-confirm)” below                                                                                                                                                                                                                                                         |
| <mark style="color:blue;">URL Matching Rules</mark>           | Crawl only URLs that match the rules, such as `/products/*`. If no rules are added, all pages within the scope will be crawled                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                               |
| <mark style="color:blue;">URL Exclusion Rules</mark>          | Do not crawl URLs that match the rules, such as `/admin/*` or `\.pdf$`                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                       |
| <mark style="color:blue;">Boundary Settings</mark>            | Whether to <mark style="color:blue;">Allow Crawling of Same-Level or Parent Paths</mark>, <mark style="color:blue;">Include Subdomains</mark>, and <mark style="color:blue;">Allow External Links</mark>. All are off by default                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                             |
| <mark style="color:blue;">Sitemap Strategy</mark>             | <mark style="color:blue;">Prefer Sitemap (Default)</mark>, <mark style="color:blue;">Ignore Sitemap</mark>, or <mark style="color:blue;">Use Sitemap Only</mark>                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                             |
| <mark style="color:blue;">Content Extraction Settings</mark>  | <mark style="color:blue;">Extract Main Content Only</mark> and <mark style="color:blue;">Ignore URL Parameters</mark> (both on by default), plus <mark style="color:blue;">JS Rendering Wait Time</mark> (0, 500, 1000, or 2000 ms)                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                          |
| <mark style="color:blue;">Crawl Language/Region</mark>        | Read the website using a specified language and region. Multilingual websites return the corresponding language version; for example, choosing <mark style="color:blue;">Traditional Chinese (Taiwan)</mark> can prevent a redirect to the English version. Options include <mark style="color:blue;">Traditional Chinese (Taiwan)</mark>, <mark style="color:blue;">Simplified Chinese (China)</mark>, <mark style="color:blue;">English (US)</mark>, and <mark style="color:blue;">Japanese (Japan)</mark>. <mark style="color:blue;">Default (Unspecified)</mark> does not declare a language to the website; the crawl service decides (currently equivalent to English). This setting is below <mark style="color:blue;">Content Extraction Settings</mark>. Previews and every scheduled run use the same locale. See [Multilingual Websites: Specify the Crawl Language/Region](/maiagent-user-guide/en/build/knowledge-base/crawler.md#crawl-locale) |

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-ea33308d14838c70084cba9240919e27688ce38c%2Fcrawl-create-advanced-settings.png?alt=media" alt="Expanded Advanced Settings in the Crawl Settings step, including prompt-based rule generation, URL matching rules, URL exclusion rules, boundary settings, sitemap strategy, content extraction settings, and crawl language/region (Default (Unspecified)) below content extraction settings"><figcaption><p>Advanced Settings: Further limit the crawl scope with URL rules, boundaries, and sitemap strategy, and specify a crawl language/region</p></figcaption></figure>

{% hint style="warning" %}
Enabling <mark style="color:blue;">Allow External Links</mark> crawls URLs outside the website, which may significantly increase the page count and cost. Test with a small depth and page limit first, then increase them after confirming the scope.
{% endhint %}

{% hint style="info" %}
Prompts only generate URL matching/exclusion rules; they cannot filter by page title or body text. For lists that paginate using buttons or forms without changing the URL, the crawler can only collect the first page.
{% endhint %}

#### Confirmation When a Prompt Has Not Generated Rules <a href="#prompt-not-generated-confirm" id="prompt-not-generated-confirm"></a>

If you fill in <mark style="color:blue;">Generate Rules from a Prompt</mark> but click <mark style="color:blue;">Next</mark> or <mark style="color:blue;">Preview</mark> before clicking <mark style="color:blue;">Generate Rules</mark> (or after editing the prompt again following generation), the system first opens a “Prompt Has Not Been Converted to Rules” confirmation dialog. It warns that continuing directly will crawl all pages within the scope:

* <mark style="color:blue;">Generate Rules</mark>: Generate URL rules from the prompt. If the dialog appears from <mark style="color:blue;">Preview</mark>, you first return to the “Crawl Settings” step to generate rules so you can review them before previewing again
* <mark style="color:blue;">Continue Anyway</mark>: Continue with the current settings without generating rules
* Close the dialog in the upper right or press Esc: Stay on the current step without taking any action

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-7f8055a4cfe839de6bbcdb293681827d151388cf%2Fcrawl-create-prompt-confirm.png?alt=media" alt="The Prompt Has Not Been Converted to Rules confirmation dialog warns that continuing directly will crawl all pages within the scope, with Continue Anyway and Generate Rules buttons below"><figcaption><p>The confirmation dialog that appears when you click Next before generating rules from the prompt</p></figcaption></figure>

{% hint style="info" %}
Only changes to the prompt itself trigger confirmation. Manually adding or deleting <mark style="color:blue;">URL Matching Rules</mark> or <mark style="color:blue;">URL Exclusion Rules</mark> after generation does not count as a prompt change and will not trigger another confirmation. If you select <mark style="color:blue;">Continue Anyway</mark> at <mark style="color:blue;">Next</mark>, you will still be asked again when you click <mark style="color:blue;">Preview</mark> in “Execution Method.”
{% endhint %}

For example, a company's knowledge management specialist wants to crawl documentation under `/docs/` on the company website into a knowledge base. She enters “Only collect pages under /docs/ and exclude PDFs” in the prompt and immediately clicks <mark style="color:blue;">Next</mark>. When the confirmation dialog appears, she selects <mark style="color:blue;">Generate Rules</mark>. The rules section then shows a `/docs/.*` matching rule and a `.*\.pdf$` exclusion rule. Clicking <mark style="color:blue;">Next</mark> again does not repeat the question, helping prevent accidentally crawling the entire website into the knowledge base.

#### How the Crawl Scope Is Determined <a href="#crawl-scope-rules" id="crawl-scope-rules"></a>

The crawler starts at the starting URL and follows links on pages to discover more URLs. A URL must meet all of the following conditions to be crawled:

| Condition         | Rule                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                |
| ----------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Within-site scope | By default, only pages with the same hostname and paths under the starting URL are crawled (if the starting URL is `https://example.com/docs/`, `/docs/a` is crawled but `/blog/` is not). <mark style="color:blue;">Allow Crawling of Same-Level or Parent Paths</mark> expands the scope to the entire domain; <mark style="color:blue;">Include Subdomains</mark> also includes subdomains such as `help.example.com`; <mark style="color:blue;">Allow External Links</mark> is required to crawl other websites |
| URL rules         | <mark style="color:blue;">URL Exclusion Rules</mark> take priority over <mark style="color:blue;">URL Matching Rules</mark>. Once matching rules are set, URLs that do not match any rule are not crawled. Rules are regular expressions and, by default, match only the URL path (excluding the hostname and parameters)                                                                                                                                                                                           |
| Depth             | <mark style="color:blue;">Maximum Crawl Depth</mark> counts levels in the “discovery order”: The starting URL and URLs listed in the sitemap are level 0, pages linked from them are level 1, pages linked from those are level 2, and so on. Discovery stops beyond the configured depth                                                                                                                                                                                                                           |
| Page count        | <mark style="color:blue;">Maximum Pages to Crawl</mark> is the total page limit for this crawl. Crawling stops when the limit is reached, regardless of depth                                                                                                                                                                                                                                                                                                                                                       |
| Sitemap           | The default is <mark style="color:blue;">Prefer Sitemap</mark>: If the website has a sitemap, its URLs are included directly (as level 0), even if the starting page does not link to them. <mark style="color:blue;">Ignore Sitemap</mark> follows links only; <mark style="color:blue;">Use Sitemap Only</mark> crawls only URLs listed in the sitemap                                                                                                                                                            |
| URL parameters    | When <mark style="color:blue;">Ignore URL Parameters</mark> is on, URLs that differ only in parameters, such as `?page=2`, are treated as the same page and crawled once. Turn this off for websites that use parameters to switch page content                                                                                                                                                                                                                                                                     |
| robots.txt        | The crawler always follows the target website's robots.txt. Disallowed paths are not crawled, and settings cannot bypass this restriction                                                                                                                                                                                                                                                                                                                                                                           |

Each URL is processed only once per crawl, even if multiple pages link to it.

**To collect only the starting page**: Set the sitemap strategy to <mark style="color:blue;">Ignore Sitemap</mark>, set maximum crawl depth to 1, and add a <mark style="color:blue;">URL Matching Rule</mark> that matches only that page's path (for example, `^/about/?$`). Then use <mark style="color:blue;">Preview</mark> to confirm that only this page appears under “Will Crawl.”

When finished, click <mark style="color:blue;">Next</mark>.

### 4. Choose an Execution Method and Knowledge Base Import <a href="#step-execution" id="step-execution"></a>

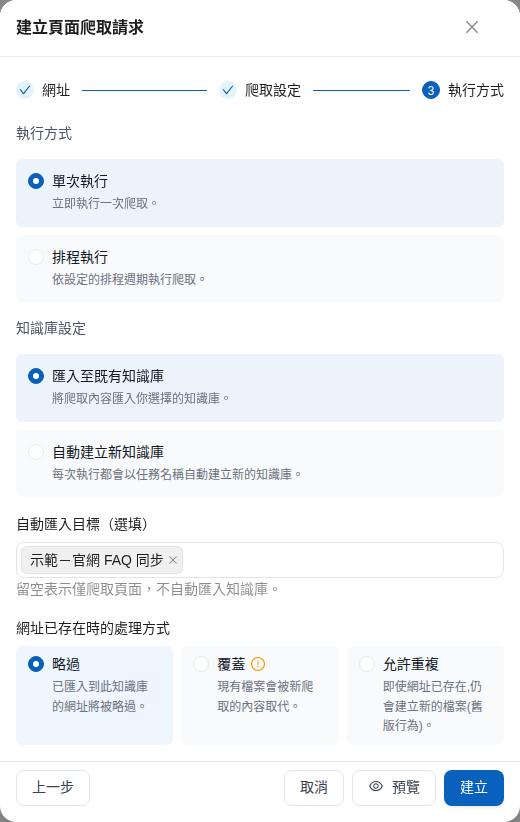
The third step, “Execution Method,” determines when to crawl and where to import the results.

**Execution Method**

* <mark style="color:blue;">One-Time Run</mark>: Run one crawl immediately after creation
* <mark style="color:blue;">Scheduled Run</mark>: Crawl according to the configured schedule (see “[Set Up a Recurring Schedule](#schedule)” in the next section)

**Knowledge Base Settings**

* <mark style="color:blue;">Import into an Existing Knowledge Base</mark>: Select one or more knowledge bases under <mark style="color:blue;">Automatic Import Destination (Optional)</mark> for automatic import after crawling. Leave this blank to crawl pages without automatically importing them; you can [import manually](#manual-import) later
* <mark style="color:blue;">Automatically Create a New Knowledge Base</mark>: Create a new knowledge base with the task name for every run and import the crawled content into it

After selecting an import destination, <mark style="color:blue;">Handling Existing URLs</mark> appears to control what happens when the same URL has already been imported into that knowledge base:

| Option                                            | Description                                          |
| ------------------------------------------------- | ---------------------------------------------------- |
| <mark style="color:blue;">Skip</mark> (default)   | Skip URLs already imported into this knowledge base  |
| <mark style="color:blue;">Overwrite</mark>        | Replace the existing file with newly crawled content |
| <mark style="color:blue;">Allow Duplicates</mark> | Create a new file even if the URL already exists     |

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-b849114622ef4fe018592ac55f4824c782ab52d5%2Fcrawl-create-execution-oneshot.png?alt=media" alt="The Execution Method step with One-Time Run and Import into an Existing Knowledge Base selected, showing Handling Existing URLs with Skip as the default"><figcaption><p>Execution Method: Choose a one-time run and specify the knowledge base for automatic import and how to handle duplicate URLs</p></figcaption></figure>

{% hint style="info" %}
For recurring synchronization of the same website, use <mark style="color:blue;">Skip</mark> or <mark style="color:blue;">Overwrite</mark> to avoid accumulating duplicate files in the knowledge base that could cause the Agent to cite outdated content.
{% endhint %}

### 5. Preview and Create <a href="#preview-and-create" id="preview-and-create"></a>

Before creating the request, click <mark style="color:blue;">Preview</mark> to check which pages will actually be crawled. A preview explores website URLs and incurs a charge. A confirmation dialog appears first; the preview runs only after you click <mark style="color:blue;">Confirm</mark>.

The preview shows the number of discovered URLs, URLs to crawl and exclude, estimated page count and duration, and a list of pages to crawl.

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-98ade6f0b412295b27e59ddb54058d43ec4ade6b%2Fcrawl-preview.png?alt=media" alt="The preview dialog shows the target URL, counts of discovered URLs, URLs to crawl and exclude, estimated page count and duration, and the list of pages to crawl"><figcaption><p>Preview: Check the number and list of pages to crawl before creating the request</p></figcaption></figure>

{% hint style="info" %}
The preview is an estimate. The actual crawl may vary slightly due to depth limits, JavaScript-generated pages, and robots.txt.
{% endhint %}

After confirming the settings, click <mark style="color:blue;">Create</mark>. A one-time request appears on the “Page Crawl Requests” tab and begins crawling.

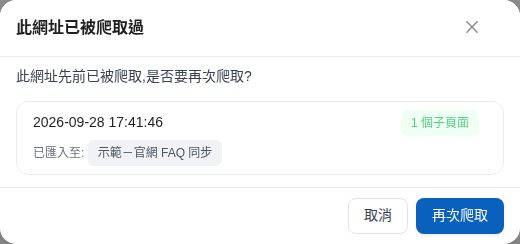
If the URL has been crawled before, the system opens a <mark style="color:blue;">This URL Has Been Crawled Before</mark> confirmation dialog listing the previous crawl time, page count, and knowledge bases it was imported into. Click <mark style="color:blue;">Crawl Again</mark> to crawl it again, or <mark style="color:blue;">Cancel</mark> if another crawl is unnecessary.

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-1701750793d8cd036def10ccfdc6c13d6294e3a0%2Fcrawl-previously-crawled.png?alt=media" alt="The This URL Has Been Crawled Before confirmation dialog lists the previous crawl time, subpage count, and knowledge bases it was imported into"><figcaption><p>Repeat crawl reminder: Review previous crawl results before deciding whether to crawl again</p></figcaption></figure>

## Set Up a Recurring Schedule <a href="#schedule" id="schedule"></a>

For websites with regularly updated content, select <mark style="color:blue;">Scheduled Run</mark> in the third step to have the system crawl again periodically and automatically import into a knowledge base.

| Field                                                                                 | Description                                                                                                                                                         |
| ------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| <mark style="color:blue;">Frequency</mark>                                            | <mark style="color:blue;">Once</mark>, <mark style="color:blue;">Daily</mark>, <mark style="color:blue;">Weekly</mark>, or <mark style="color:blue;">Monthly</mark> |
| <mark style="color:blue;">Time Zone</mark>                                            | The time zone used for scheduled times                                                                                                                              |
| <mark style="color:blue;">Start Date</mark>/<mark style="color:blue;">End Date</mark> | The period during which the schedule is active. End date is optional; only a start date is needed for “Once”                                                        |
| <mark style="color:blue;">Run Time</mark>                                             | The time of each run                                                                                                                                                |
| <mark style="color:blue;">Days of the Week</mark>                                     | For “Weekly,” select the days to run (multiple selections allowed)                                                                                                  |
| <mark style="color:blue;">Day of the Month</mark>                                     | For “Monthly,” enter 1–31                                                                                                                                           |

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-2d4abe505f3c1a4ac079e7c5eabefd3ebea96cdb%2Fcrawl-create-execution-schedule.png?alt=media" alt="Scheduled Run settings with Weekly frequency, Asia/Taipei time zone, 09:00 run time, Monday selected, and import into an existing knowledge base"><figcaption><p>Scheduled Run: Automatically crawl and import into a knowledge base every Monday at 9 a.m.</p></figcaption></figure>

After creation, the schedule appears on the <mark style="color:blue;">Schedules</mark> tab with its settings and status (<mark style="color:blue;">Active</mark>/<mark style="color:blue;">Paused</mark>). The icons in the actions column, in order, let you:

* **Edit**: Open “Edit Schedule” to change the task name, crawl settings, scheduled time, and knowledge base settings (the starting URL cannot be changed after creation)
* **Run History**: View the time and crawl status of each scheduled run and open its crawl details
* **Pause/Enable**: Temporarily stop the schedule or enable it again
* **Delete**: Delete the schedule

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-a004c12c146f1a0a9fae14b5ee685e937d16b530%2Fcrawl-schedule-list.png?alt=media" alt="The Schedules tab lists an active schedule that runs every Monday at 9:00, with Edit, Run History, Pause, and Delete icons in the actions column"><figcaption><p>Schedules tab: View schedule settings, edit them, check run history, pause, or delete</p></figcaption></figure>

{% hint style="warning" %}
Every scheduled run actually crawls pages and consumes Credits. Pause the schedule when synchronization is temporarily unnecessary.
{% endhint %}

## View Crawl Results and Import History <a href="#results-and-import-history" id="results-and-import-history"></a>

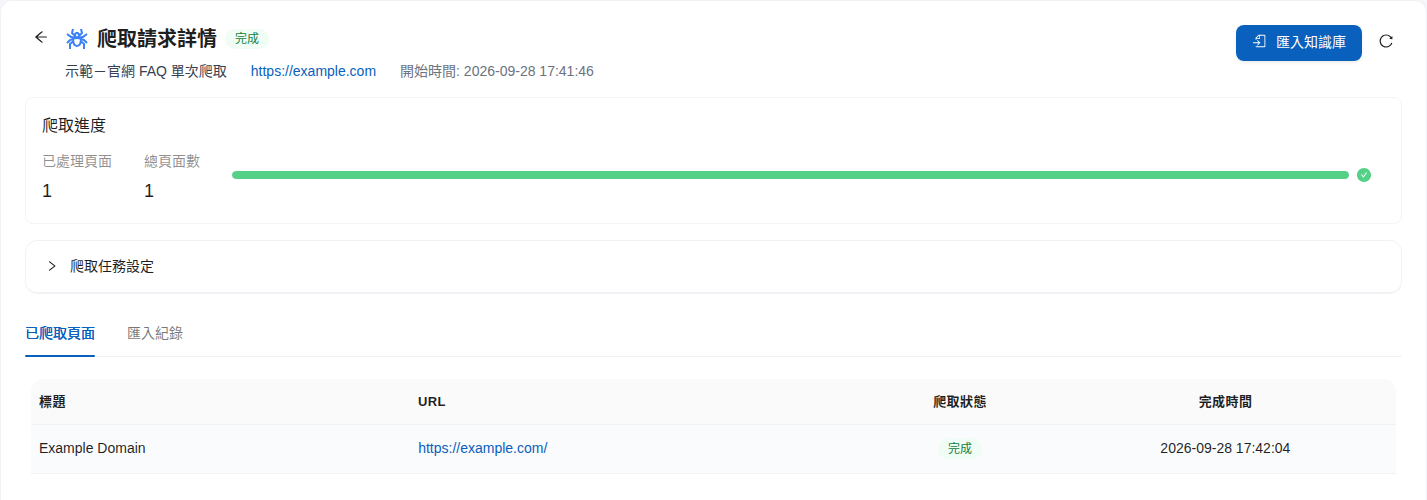
On the “Page Crawl Requests” tab, click <mark style="color:blue;">Details</mark> for a request to open the <mark style="color:blue;">Crawl Request Details</mark> page:

* <mark style="color:blue;">Crawl Progress</mark>: Processed pages and total page count
* <mark style="color:blue;">Crawl Task Settings</mark>: Expand to review the URL, crawl settings, and execution method used at creation. Switch to “Crawl Settings” to see the <mark style="color:blue;">Crawl Language/Region</mark> used for this run (“Default (Unspecified)” if not set)
* <mark style="color:blue;">Crawled Pages</mark>: Lists the title, URL, crawl status, and completion time of each crawled page

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-0d2fa9e3af7c9c17622c9a76458e1535b3a2f8f8%2Fcrawl-detail.png?alt=media" alt="The Crawl Request Details page shows crawl progress, crawl task settings, and a list of crawled pages"><figcaption><p>Crawl Request Details: View crawl progress and crawled pages</p></figcaption></figure>

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-5c79ddd8513569f8e090b2f8f926a1d2a7dedb09%2Fcrawl-detail-locale.png?alt=media" alt="The content extraction section in Crawl Task Settings displays Traditional Chinese (Taiwan) as the read-only crawl language/region, with one completed page bearing a Chinese title listed under Crawled Pages"><figcaption><p>Crawl Task Settings: Read-only display of the crawl language/region used for this run</p></figcaption></figure>

Switch to the <mark style="color:blue;">Import History</mark> tab to see the time, destination knowledge base, <mark style="color:blue;">Import Method</mark> (shown as “Automatic” for automatic imports based on the creation settings), and successful and failed page counts for each import.

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-e7cd87be7b457d330db2ca3192ca780cf6fb4cab%2Fcrawl-import-history.png?alt=media" alt="The Import History tab shows one import into a demo knowledge base with Automatic as the import method, 1 successful page, and 0 failed pages"><figcaption><p>Import History: Destination knowledge base, import method, and successful/failed page counts for each import</p></figcaption></figure>

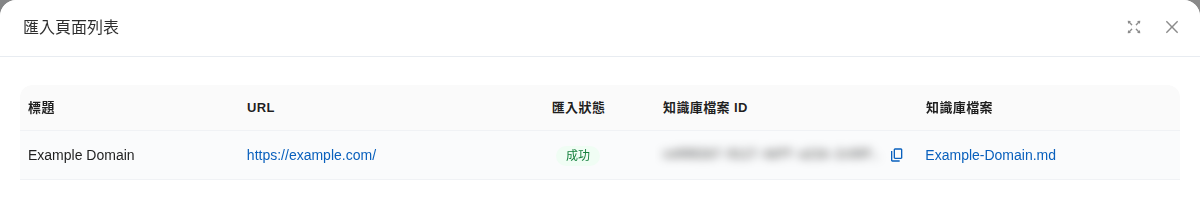
Click the icon in the actions column to open the <mark style="color:blue;">Imported Pages List</mark> and check each page's import status and corresponding knowledge base file.

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-776aee0d55309e3f78688782e1f8b4c84cbd41f7%2Fcrawl-import-run-pages.png?alt=media" alt="The Imported Pages List dialog lists page titles, URLs, successful import statuses, and corresponding knowledge base files"><figcaption><p>Imported Pages List: Check the knowledge base file corresponding to each imported page</p></figcaption></figure>

For completed requests in the “Page Crawl Requests” list, you can also click <mark style="color:blue;">View</mark> to open <mark style="color:blue;">Failed Import History</mark>, select a knowledge base, and check failed pages and the reasons for failure.

Imported content appears as .md files in the knowledge base's document list (with filenames based on page titles). You can set tags and metadata just as for other documents. These files display a <mark style="color:blue;">Crawler</mark> label in the <mark style="color:blue;">Source</mark> column; click it to return to the corresponding crawl request details. The system also writes the source URL into the document's `url` metadata. When the Agent cites the document, clicking the citation opens the original webpage. For how content is preserved, see [Knowledge Base Overview FAQ](/maiagent-user-guide/en/build/knowledge-base/km.md#faq-format-preservation).

## Manually Import Crawled Pages <a href="#manual-import" id="manual-import"></a>

If you did not configure automatic import at creation, or want to import pages into other knowledge bases, you can import manually:

1. On the crawl request details page, click <mark style="color:blue;">Import into Knowledge Base</mark> (or click <mark style="color:blue;">Import</mark> for the request in the list)
2. Select the destination <mark style="color:blue;">Knowledge Base</mark> and choose <mark style="color:blue;">Handling Existing URLs</mark>
3. Select the pages to import and click <mark style="color:blue;">Import</mark>

<figure><img src="https://1360999650-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F6v6TNkkOQVfRYfcNirHL%2Fuploads%2Fgit-blob-b84abfbe106ef4aab81f035bee907c9c9c77b2e2%2Fcrawl-manual-import.png?alt=media" alt="The page list dialog with selections for knowledge base, handling existing URLs, and pages to import"><figcaption><p>Manual Import: Select a knowledge base, duplicate URL handling, and pages to import</p></figcaption></figure>

If you choose <mark style="color:blue;">Skip</mark> and some URLs have already been imported, the system reports how many import tasks were created and how many duplicate URLs were skipped.

{% hint style="warning" %}
Manual import crawls the latest page data again and incurs a crawl charge.
{% endhint %}

## Investigate Crawl or Import Failures <a href="#troubleshooting" id="troubleshooting"></a>

First identify which stage failed, then check the cause:

| Symptom                                                                                            | Common causes                                                                                                                                                            | What to do                                                                                                                                                                                                                                                                                                    |
| -------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| The request is blocked when you create it                                                          | The starting URL exceeds 200 characters or is not a complete URL (it must include `http://` or `https://`)                                                               | Use a shorter parent URL as the starting point, then use crawl depth and matching rules to cover the target pages                                                                                                                                                                                             |
| The crawl status is Failed, with the reason “The crawl has finished, but no pages were retrieved”  | The target website's robots.txt disallows crawling (the reason lists the blocked URLs); the website blocks automated access; the starting URL cannot be loaded           | Check that the URL opens in a browser without logging in. If the website disallows crawling, provide the content by uploading files instead                                                                                                                                                                   |
| Fewer pages are crawled than expected                                                              | Pages fall outside the crawl domain scope, are excluded by exclusion rules, or exceed the maximum crawl depth or page count; content is loaded dynamically by JavaScript | Before creating the request, use the preview to check the URLs under “Will crawl” and “Excluded”, then adjust the depth, page count, and matching rules                                                                                                                                                       |
| Pages require a login to view                                                                      | The crawler can only read public pages                                                                                                                                   | Export the content as files and upload them to the knowledge base                                                                                                                                                                                                                                             |
| The website only allows IP addresses on its allowlist, and you want to add the crawler's source IP | Crawling is performed by a cloud crawling service with variable source IP addresses. MaiAgent cannot provide an IP address to add to an allowlist                        | Ask the website administrator to export the content as files and upload them to the knowledge base                                                                                                                                                                                                            |
| Crawling succeeds, but importing into the knowledge base fails                                     | Individual pages fail during import processing                                                                                                                           | In the “Page Crawl Requests” list, click <mark style="color:blue;">View</mark> to open <mark style="color:blue;">Failed Import Records</mark>. Select the knowledge base and check each page's <mark style="color:blue;">Failure Reason</mark>, then use [manual import](#manual-import) to import them again |

If the failure reason does not explain the issue, or the same URL fails repeatedly, note the crawl request's name and time and contact your MaiAgent representative.

## Crawler usage considerations <a href="#scraping-considerations" id="scraping-considerations"></a>

* Make sure you have permission to crawl the target website's content
* Crawling, previews, and manual imports all consume Credits. Start by testing with a lower maximum crawl depth and page count, then expand after confirming the scope
* After crawling is complete, use the [search test feature](/maiagent-user-guide/en/build/knowledge-base/test-search-result.md) to verify data quality
* If website content changes frequently, use a [recurring schedule](#schedule) to keep information up to date, along with <mark style="color:blue;">Skip</mark> or <mark style="color:blue;">Overwrite</mark> to avoid duplicate files


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://docs.maiagent.ai/maiagent-user-guide/en/build/knowledge-base/scrape-website.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.